Model-agnostic
One agentic workflow across different base models.
Let the model’s feedback shape what it learns next.
Post-training is crucial for improving text-to-image models, yet existing pipelines typically rely on manually curated training data and fixed training distributions. We introduce APT (Agentic Post-Training), a fully automated framework that adaptively post-trains a base model according to its evolving capability profile. APT coordinates three agents to construct evaluation sets from user requirements, diagnose model-specific strengths and failure modes, and generate reinforcement learning data with an adaptive prompt distribution that emphasizes underperforming capabilities. By repeatedly evaluating, diagnosing, and updating the generator, APT lets the current model’s behavior shape its next training tasks, forming a feedback loop inspired by recursive self-improvement. For general-purpose settings without user-specified evaluation scenarios, we further develop an evaluation harness that enables broad and diverse evaluation set generation. Experiments across multiple base models, benchmarks, and generation architectures demonstrate that APT is model-agnostic, benchmark-agnostic, architecture-agnostic, and fully automated.
Generated by different base models, post-trained with the same APT workflow. See comparisons
01 / The idea
Different image models struggle with different things. A fixed training set cannot keep up with every model’s evolving strengths and weaknesses.
APT makes post-training adaptive. Three agents work together to evaluate the current model, diagnose its failure modes, and generate the training prompts it needs next. After each update, the loop starts again.
One agentic workflow across different base models.
One post-trained model, evaluated on multiple benchmarks.
Works with diffusion and autoregressive generators.
Model feedback drives the next round of training data.
02 / The method
APT (Agentic Post-Training) turns post-training into a fully automated, evaluation-driven adaptive loop. Given a user-specified evaluation scope, the Evaluation Set Generation Agent constructs a diverse evaluation set consisting of prompt–evaluation rubric pairs; the Diagnosis Agent evaluates the current model on these pairs to identify its strengths and failure modes; and the RL Data Generation Agent adaptively samples next-round training prompts, prioritizing underperforming capabilities. The updated model is then re-evaluated in the next round, allowing the training distribution to continuously adapt to the model's evolving capability profile. This design eliminates the need for manually curated post-training data and makes APT model-agnostic, benchmark-agnostic, architecture-agnostic, and fully automated.
Starting from a user-specified scope—or a general-purpose evaluation harness—the agent builds a diverse taxonomy of scenarios, then generates prompts and task-specific evaluation rubrics. This evaluation set stays fixed throughout post-training.
Output: a fixed evaluation set of prompt–rubric pairs.
120 diagnostic prompts → 480 training prompts → 20 RL steps per round

Left: Statistics of the sub-categories within each category and the prompt-rubrics pairs within each category. All prompt-rubrics pairs are automatically generated by our Evaluation Set Generation Agent, providing comprehensive coverage for evaluating the current T2I model. Right: An example prompt-rubrics pair.
03 / The evidence
APT achieves the best average performance across all four diffusion models, outperforming post-training on a carefully handcrafted RL set.
For the normalized average, GenEval, OneIG-EN, and CVTG-2K are rescaled to 0–100, then averaged with GenEval2 and DPG. No benchmark prompts are used to construct the main APT training data.
Lens average over its base model
FLUX.1 [dev] average over its base model
Diffusion models with the best average using APT
| Model | Setting | GenEval | OneIG-EN | GenEval2 | DPG | CVTG-2K | Average |
|---|
APT also improves the autoregressive Janus-Pro model with GRPO, outperforming the base and handcrafted RL settings on the three reported overall metrics.
| Metric | Base | Handcrafted RL | APT |
|---|---|---|---|
| GenEval | 0.781 | 0.806 | 0.815 |
| OneIG-EN | 0.314 | 0.316 | 0.318 |
| GenEval2 | 15.25 | 20.42 | 21.61 |
04 / Why adaptation matters
Post-train each target with its own adaptively generated data or with data generated for another model. Target-adaptive data gives the best three-benchmark average in every row.
Source model for APT-generated RL data →
| Target ↓ | Lens | SD3.5 | FLUX | LongCat |
|---|---|---|---|---|
| Lens | 61.40 | 60.03 | 60.88 | 58.93 |
| SD3.5 | 45.87 | 47.43 | 46.15 | 44.78 |
| FLUX | 47.19 | 48.53 | 50.67 | 48.97 |
| LongCat | 56.04 | 55.19 | 56.13 | 57.07 |
Adapted to the target model · Best average in every row
Normalized average over three benchmarks: GenEval, OneIG-EN, and GenEval2. All models use 200 optimization steps in this study.
Lens, SD3.5-Medium, FLUX, and LongCat all achieve their highest average when the training data is generated adaptively for the same target model.
Target-adaptive training gains 0.52–1.70 normalized-average points over the best transferred source. For FLUX, the score rises from 48.97 to 50.67.
Data suited to one generator’s failure modes is suboptimal for another. These results support diagnosing and generating RL data for the model being updated.
Columns identify the source of the training data; rows identify the target model. Shading marks target-adaptive training, and bold marks the best score in each row. Each target model is trained for 200 optimization steps.
| Target ↓ | Lens | SD3.5 | FLUX | LongCat |
|---|---|---|---|---|
| Lens | 0.851 | 0.833 | 0.846 | 0.798 |
| SD3.5 | 0.736 | 0.743 | 0.742 | 0.722 |
| FLUX | 0.679 | 0.726 | 0.751 | 0.729 |
| LongCat | 0.823 | 0.786 | 0.827 | 0.828 |
| Target ↓ | Lens | SD3.5 | FLUX | LongCat |
|---|---|---|---|---|
| Lens | 0.523 | 0.522 | 0.517 | 0.520 |
| SD3.5 | 0.404 | 0.404 | 0.405 | 0.395 |
| FLUX | 0.436 | 0.443 | 0.459 | 0.440 |
| LongCat | 0.509 | 0.496 | 0.508 | 0.506 |
| Target ↓ | Lens | SD3.5 | FLUX | LongCat |
|---|---|---|---|---|
| Lens | 46.80 | 44.59 | 46.35 | 44.98 |
| SD3.5 | 23.61 | 27.58 | 23.74 | 22.65 |
| FLUX | 30.06 | 28.69 | 31.01 | 30.02 |
| LongCat | 34.91 | 37.37 | 34.90 | 37.80 |
05 / Ablation studies
01 / Evaluation coverage
Replace the APT-generated evaluation set with OneIG-EN or GenEval when diagnosing the model, while keeping the remaining pipeline unchanged. The APT evaluation set achieves the best five-benchmark average for both base models.
Scroll horizontally for all benchmark scores
| Evaluation setting | GenEvalOverall | OneIG-ENAverage | GenEval2Soft-TIFAGM | DPGOverall | CVTG-2KWord accuracy | AverageNormalized |
|---|---|---|---|---|---|---|
| Lens | ||||||
| Base Model | 0.702 | 0.521 | 29.06 | 85.93 | 0.480 | 57.06 |
| OneIG-EN Evaluation Set | 0.847 | 0.528 | 47.08 | 87.39 | 0.823 | 70.85 |
| GenEval Evaluation Set | 0.887 | 0.505 | 41.43 | 84.23 | 0.674 | 66.45 |
| APT Evaluation Set | 0.859 | 0.523 | 50.73 | 87.88 | 0.795 | 71.26 |
| SD3.5-Medium | ||||||
| Base Model | 0.684 | 0.408 | 17.63 | 83.67 | 0.312 | 48.34 |
| OneIG-EN Evaluation Set | 0.800 | 0.431 | 26.38 | 86.69 | 0.497 | 57.17 |
| GenEval Evaluation Set | 0.692 | 0.390 | 17.35 | 79.02 | 0.458 | 50.07 |
| APT Evaluation Set | 0.763 | 0.404 | 29.50 | 86.50 | 0.569 | 57.92 |
02 / Feedback & curriculum
On Lens, remove repeated diagnosis, reduce the diagnostic criteria, or train only on difficult capabilities. The full APT setting combines refreshed feedback with comprehensive diagnosis and balanced prompt sampling.
Scroll horizontally for all benchmark scores
| Post-training setting | GenEvalOverall | OneIG-ENAverage | GenEval2Soft-TIFAGM | DPGOverall | CVTG-2KWord accuracy | AverageNormalized |
|---|---|---|---|---|---|---|
| Lens | ||||||
| APTFull framework | 0.859 | 0.523 | 50.73 | 87.88 | 0.795 | 71.26 |
| w/o Iterative Feedback LoopIterative feedback ablation | 0.844 | 0.523 | 48.27 | 87.61 | 0.791 | 70.34 |
| Reduced Diagnostic CriteriaRL data generation ablation | 0.800 | 0.520 | 49.58 | 87.53 | 0.763 | 69.08 |
| Hard-Only SamplingRL data generation ablation | 0.853 | 0.530 | 47.91 | 87.58 | 0.794 | 70.64 |
Without iterative feedback
Reduced diagnostic criteria
Hard-only sampling
03 / Agent backbone robustness
Use Lens as the image generator and change only the LLM in the RL Data Generation Agent. All eight tested backbones improve the five-benchmark average over the base model; GPT-5.4 is the default backbone.
Scroll horizontally for all benchmark scores
| Data-generation LLM | GenEvalOverall | OneIG-ENAverage | GenEval2Soft-TIFAGM | DPGOverall | CVTG-2KWord accuracy | AverageNormalized |
|---|---|---|---|---|---|---|
| Lens | ||||||
| Base ModelBefore post-training | 0.702 | 0.521 | 29.06 | 85.93 | 0.480 | 57.06 |
| GPT-5.4Default data-generation backbone | 0.859 | 0.523 | 50.73 | 87.88 | 0.795 | 71.26 |
| GPT-5.6-Sol | 0.832 | 0.519 | 51.43 | 88.12 | 0.791 | 70.75 |
| GPT-4.1 | 0.851 | 0.520 | 48.94 | 87.93 | 0.796 | 70.71 |
| GPT-5.4-mini | 0.825 | 0.518 | 50.79 | 87.69 | 0.810 | 70.76 |
| Qwen3.5-9B | 0.861 | 0.520 | 47.03 | 88.36 | 0.793 | 70.56 |
| Qwen3.5-122B-A10B | 0.893 | 0.525 | 51.42 | 87.65 | 0.805 | 72.27 |
| Gemini-3.8-Flash | 0.829 | 0.525 | 48.67 | 87.70 | 0.781 | 69.97 |
| Grok-4.6 | 0.819 | 0.501 | 51.44 | 87.50 | 0.732 | 68.83 |
06 / See the difference
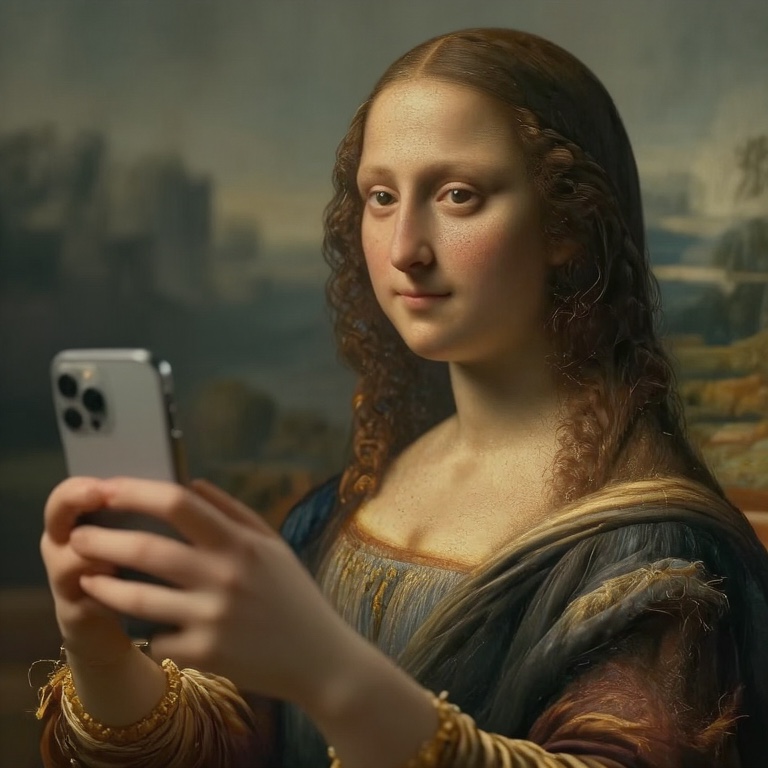
A digitally rendered image of the iconic Monalisa capturing a selfie, boasting 8K resolution and hyper-realistic details that highlight the delicate textures of her skin and the intricate fibers of her clothing. The scene is illuminated with cinematic lighting that casts soft shadows and enhances the depth of field, giving a three-dimensional quality to the image. The background is blurred artfully, drawing full attention to her enigmatic expression and the modern device in her hands, all created with the precision of an Octane render engine.
07 / Build on this work
If you find APT useful in your research,
please consider citing our work.
@misc{zhang2026aptfeedbackdrivenagenticposttraining,
  title = {APT: Feedback-Driven Agentic Post-Training
           for Text-to-Image Generation},
  author = {Sirui Zhang and Fangyun Wei and Dong Chen
            and Jinjing Zhao and Yitong Wang
            and Yunuo Chen and Baining Guo
            and Zheng-Jun Zha},
  year = {2026},
  eprint = {2610.18097},
  archivePrefix = {arXiv},
  primaryClass = {cs.CV},
  url = {https://arxiv.org/abs/2610.18097}
}